Flowfile 0.18: Multiple Formulas per Node, 80% Alteryx Coverage, PostgreSQL
One Formula node now holds an ordered list of expressions, the Alteryx converter covers 541 of 678 corpus tools and converts .yxdb files, and the catalog can run on PostgreSQL.
Three changes in 0.18.0. The seven releases before it are in the 0.17 notes.
Multiple formulas per node
A Formula node holds an ordered list of expressions, evaluated in order, so entry two can use the column entry one created. Three new columns no longer means three chained nodes.
Each row autocompletes against the input columns plus the outputs of the rows above it — in the screenshot, the rail already offers full_name_upper and full_name_len to row three. An error sits under the row that caused it, and a misspelled column gets a did-you-mean with a one-click fix. Export emits one with_columns per entry, in order.
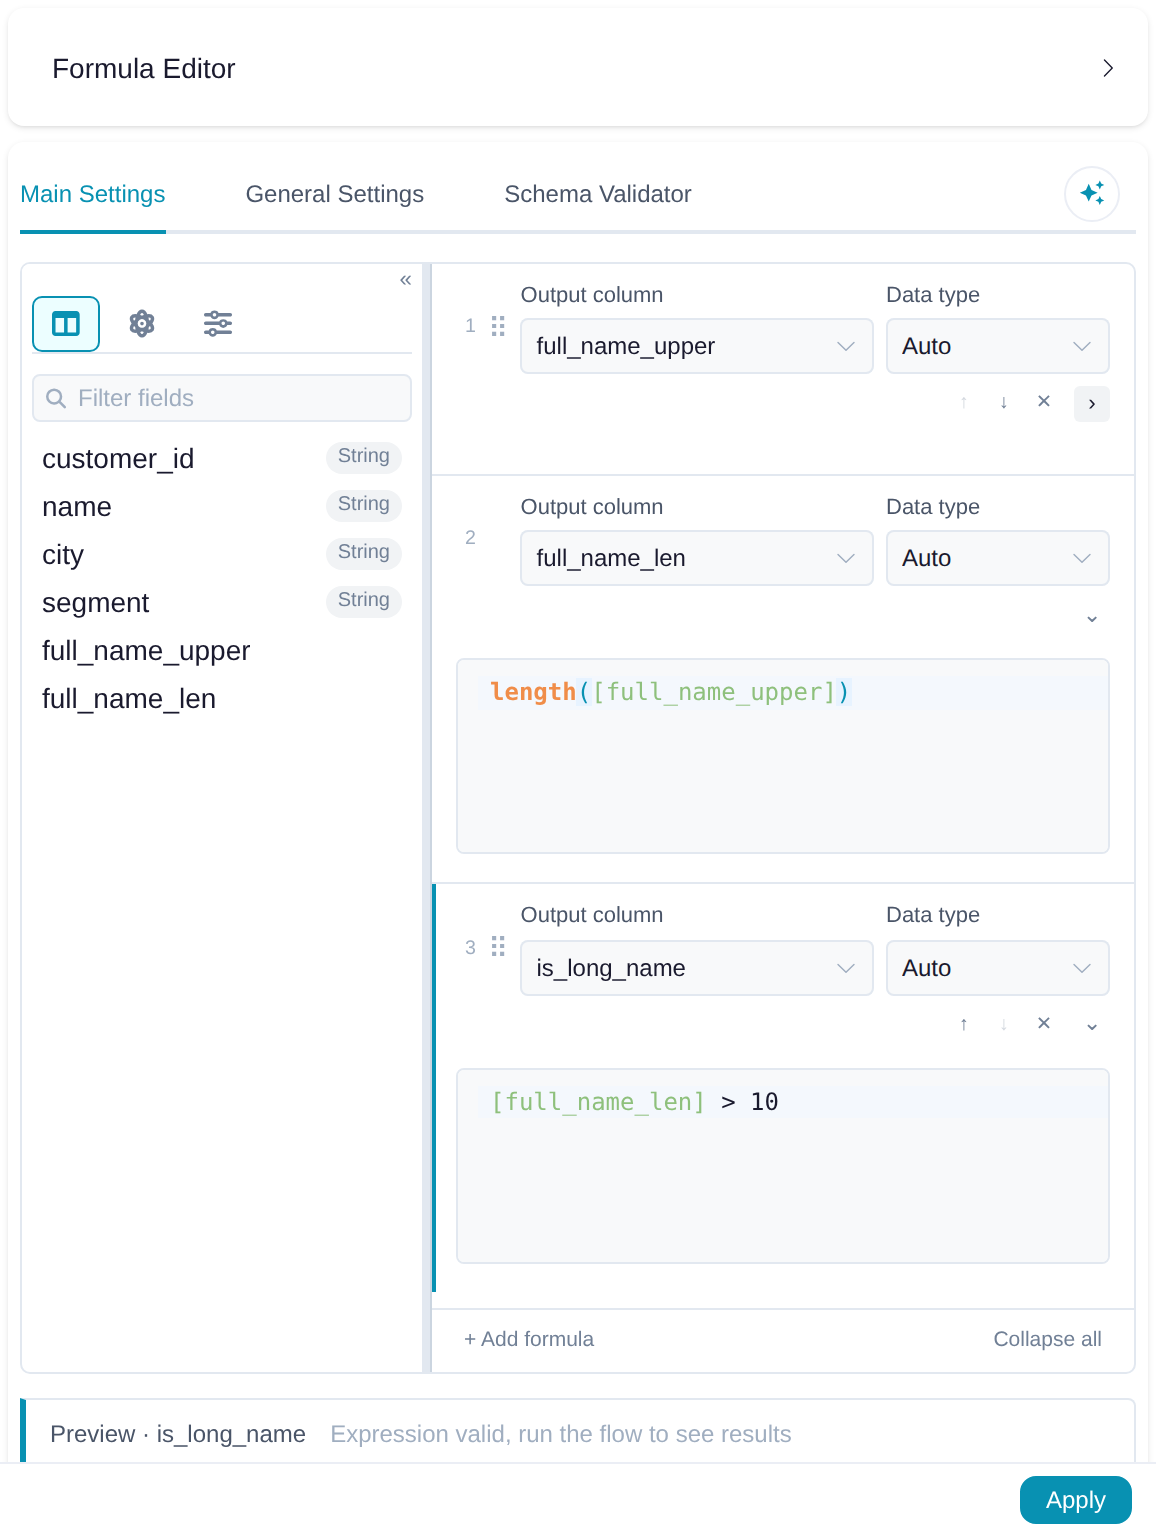
This is the opposite of 0.17’s multi-field formula, which evaluates every column in one pass against the original values. Sequential when entries build on each other; multi-field when one expression goes across columns.
Alteryx conversion: 75% to 80%
Against the converter’s test corpus, coverage went from 506 to 541 of 678 in-scope tools. New mappings:
- Reshape: CrossTab with Alteryx’s column naming, Transpose with unknown column counts
- Rows: RunningTotal, RecordID, RandomRecords, SelectRecords, the Sample modes
- Data prep: TextToColumns, AppendFields, DateTime, Rank
- Statistics: Pearson and Spearman correlation, FieldSummary, BasicDataProfile
- Filters:
REGEX_Match,PeriodAfter/PeriodBefore - Summarize: Mode, Longest, Shortest, Count Blank and Count Non Blank — the group-by node can’t express them, so they become a generated group-by instead of a placeholder
Two CLI commands: flowfile convert yxdb <file-or-dir> writes .yxdb data files out as Parquet, and flowfile import alteryx <file-or-dir> converts .yxmd workflows (--inspect reports what an import would do without writing a flow). Both take a directory. The import report itself is described in the Alteryx import post.
PostgreSQL catalog
The catalog database — catalogs, table definitions, connections, encrypted secrets, schedules, users, run history — can run on PostgreSQL 16 instead of SQLite, for Docker deployments where SQLite’s single writer becomes the bottleneck. Set it on the core container:
FLOWFILE_DATABASE_URL=postgresql+psycopg2://flowfile:password@postgres:5432/flowfileCreate the database and user first; migrations and the admin seed run on startup. Snapshots are SQLite-only, so on PostgreSQL back up with pg_dump. Table data (the Delta files) stays outside this database either way. Existing SQLite installs change nothing.
pip install flowfile, or the desktop app. Source on GitHub.
Frequently asked questions
- What share of Alteryx tools can Flowfile convert?
- 541 of the 678 in-scope tools in the converter's test corpus, about 80%, up from 75% in 0.17. A workflow built from core transforms imports cleanly; a tool without a mapping becomes a placeholder node carrying its original configuration, to finish by hand.
- Can Flowfile convert .yxdb files?
- Yes. flowfile convert yxdb <file-or-dir> writes them out as Parquet (CSV with --csv). No workflow import is involved.